Supervised Learning in Natural Language Processing
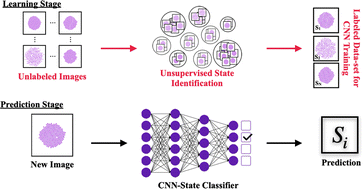
Supervised learning is one of the most widely used approaches in natural language processing (NLP). It teaches a computer to perform a language task by showing it examples that pair text with the correct answer. From identifying spam to recognizing a customer’s mood, supervised learning helps systems learn patterns from labeled data and apply them to new text.
What Is Supervised Learning?
In supervised learning, a model is trained on a collection of examples called a dataset. Each example includes an input and a target label or output. For an NLP task, the input is usually text, while the target might be a category, a value, or another piece of text.
For example, a sentiment analysis dataset might contain customer reviews labeled “positive,” “negative,” or “neutral.” During training, the model processes the reviews and learns which language patterns tend to correspond to each label. Once trained, it can predict the sentiment of reviews it has not seen before.
How the Process Works
- Define the task: Decide what the system should do, such as classify messages, identify names, or assign a topic.
- Collect and label data: Gather representative text and provide the correct answer for each example.
- Prepare the data: Clean and organize the text, and convert it into a form the model can process. Modern models often use tokenization to break text into smaller units.
- Train the model: The model compares its predictions with the supplied labels and adjusts its parameters to reduce errors.
- Evaluate performance: Test the model on examples that were not used for training to estimate how well it handles new data.
- Deploy and monitor: Use the model in an application and track its performance as language, users, or requirements change.
Common NLP Tasks That Use Supervised Learning
- Text classification: Assigning categories to documents, such as routing support requests to the right department.
- Sentiment analysis: Estimating whether text expresses a positive, negative, or neutral opinion.
- Named entity recognition: Finding and labeling names of people, organizations, locations, dates, and other entities.
- Spam detection: Classifying messages as spam or legitimate communication.
- Question answering: Selecting or generating an answer based on labeled examples and, often, a provided passage.
- Machine translation: Learning to translate text from one language to another using aligned examples of source and translated sentences.
Choosing a Model
The best model depends on the task, the amount of labeled data, available computing resources, and the accuracy required. Traditional approaches, such as logistic regression or support vector machines, can work well for simpler classification tasks, especially with carefully selected text features.
Neural networks are also common in NLP. Transformer-based models can learn rich representations of words and context, making them useful for tasks where meaning depends on surrounding text. Many modern systems begin with a model pretrained on large amounts of text and then fine-tune it using labeled examples for a specific task. This can reduce the amount of task-specific data needed, although the results still depend on the quality and relevance of the training examples.
Why Data Quality Matters
A supervised model learns from the examples it receives. If the labels are inaccurate, inconsistent, or too limited, the model may make unreliable predictions. A dataset should reflect the language and situations the system will encounter in use, including relevant variations in writing style, vocabulary, and context.
Labeling guidelines can help different annotators apply categories consistently. It is also important to check for imbalances. For example, if a dataset contains many more positive reviews than negative ones, a model may perform poorly on negative reviews unless the issue is addressed during data preparation or evaluation.
Evaluating a Supervised NLP Model
Accuracy is a useful measure when categories are evenly represented, but it can be misleading when they are not. Other measures provide a fuller picture:
- Precision: Of the items the model predicted as belonging to a category, how many were correct?
- Recall: Of all items that truly belong to a category, how many did the model find?
- F1 score: A combined measure of precision and recall.
Evaluation should use data kept separate from the training set. For a more realistic assessment, the test examples should resemble the text the model will encounter after deployment. Reviewing errors is valuable, too: it can reveal ambiguous labels, gaps in the data, or cases where the model struggles with context.
Benefits and Limitations
Supervised learning offers a clear way to teach a system a specific task. When enough reliable labeled data is available, it can produce useful and consistent predictions, and its performance can be measured against known answers.
However, creating labeled data can take time and expertise. Models may also inherit biases present in their training examples, struggle with language that differs from the data they saw, or make mistakes when faced with sarcasm, ambiguity, spelling errors, or unfamiliar topics. Performance can decline as language and real-world conditions change, so ongoing evaluation may be necessary.
Conclusion
Supervised learning is a core technique in NLP because it connects examples of language with the outputs a system is expected to produce. Its success depends on more than the choice of model: clear task definitions, representative data, consistent labels, and careful evaluation all play important roles. Used thoughtfully, supervised learning can power practical language tools while making their strengths and limitations easier to assess.
7 Essential Tips for Supervised Learning in NLP
- Use high-quality labeled text data.
- Split data into training, validation, and test sets.
- Choose a model suited to the task.
- Tokenize text consistently across datasets.
- Watch for class imbalance and data leakage.
- Track precision, recall, and task-specific metrics.
- Review errors and update labels or features.
Use high-quality labeled text data.
Using high-quality labeled text data is essential for building reliable supervised learning models in NLP. Labels should be accurate and applied consistently, while the examples should reflect the language, writing styles, and situations the model will encounter in practice. Noisy, incomplete, or unbalanced data can teach a model misleading patterns and lead to poor predictions. Clear labeling guidelines and regular quality checks can help ensure the data provides a strong foundation for training and evaluation.
Split data into training, validation, and test sets.
Split your labeled data into separate training, validation, and test sets so you can evaluate your NLP model fairly. Use the training set to teach the model, the validation set to compare approaches and tune settings, and the test set only for a final evaluation after those choices are complete. Keeping the test data untouched during development helps reveal how well the model is likely to perform on new text and reduces the risk of mistaking memorization for real learning.
Choose a model suited to the task.
Choose a model that matches the specific NLP task, the amount and type of labeled data available, and your computing resources. Simpler models, such as logistic regression, can be effective for straightforward text classification, while transformer-based models are better suited to tasks that require deeper context, such as question answering or named entity recognition. Consider accuracy, speed, cost, and ease of maintenance, then compare candidate models using evaluation data that reflects the text they will encounter in real-world use.
Tokenize text consistently across datasets.
Tokenize text consistently across datasets to ensure your NLP model processes language in the same way during training, validation, and testing. Use the same tokenizer, settings, and preprocessing rules for each dataset; otherwise, identical words or phrases may be split into different tokens, making results harder to compare and potentially reducing model performance. Consistent tokenization is especially important when working with punctuation, contractions, special characters, and multilingual text.
Watch for class imbalance and data leakage.
When training an NLP model, watch for class imbalance and data leakage. If some labels appear far more often than others, a model may favor the majority class and overlook important minority cases, so review class distributions and use suitable evaluation metrics, such as precision, recall, and F1 score. Data leakage happens when information from the test set—or details that would not be available at prediction time—sneaks into training, making results look better than they really are. Keep data splits separate, and check preprocessing steps carefully to ensure the evaluation reflects real-world performance.
Track precision, recall, and task-specific metrics.
Track precision, recall, and task-specific metrics to get a clear picture of how well your NLP model performs. Accuracy alone can hide important weaknesses, especially when some categories are much more common than others. Precision shows how often a predicted label is correct, while recall measures how many relevant examples the model successfully finds. Depending on the task, also monitor measures such as F1 score for classification, exact match for question answering, or BLEU for machine translation. Choosing metrics that reflect real-world goals helps you identify errors, compare model versions, and make improvements where they matter most.
Review errors and update labels or features.
Reviewing a model’s errors is an important part of improving supervised learning in NLP. Look for patterns in incorrect predictions, such as confusing similar categories, missing slang, or misreading context. These mistakes may point to unclear labeling guidelines, incorrect labels, gaps in the training data, or features that fail to capture useful language patterns. Correct labels and refine features where appropriate, then retrain and evaluate the model on separate data to check whether the changes improve performance without creating new problems.