The Mathematics Behind Natural Language Processing
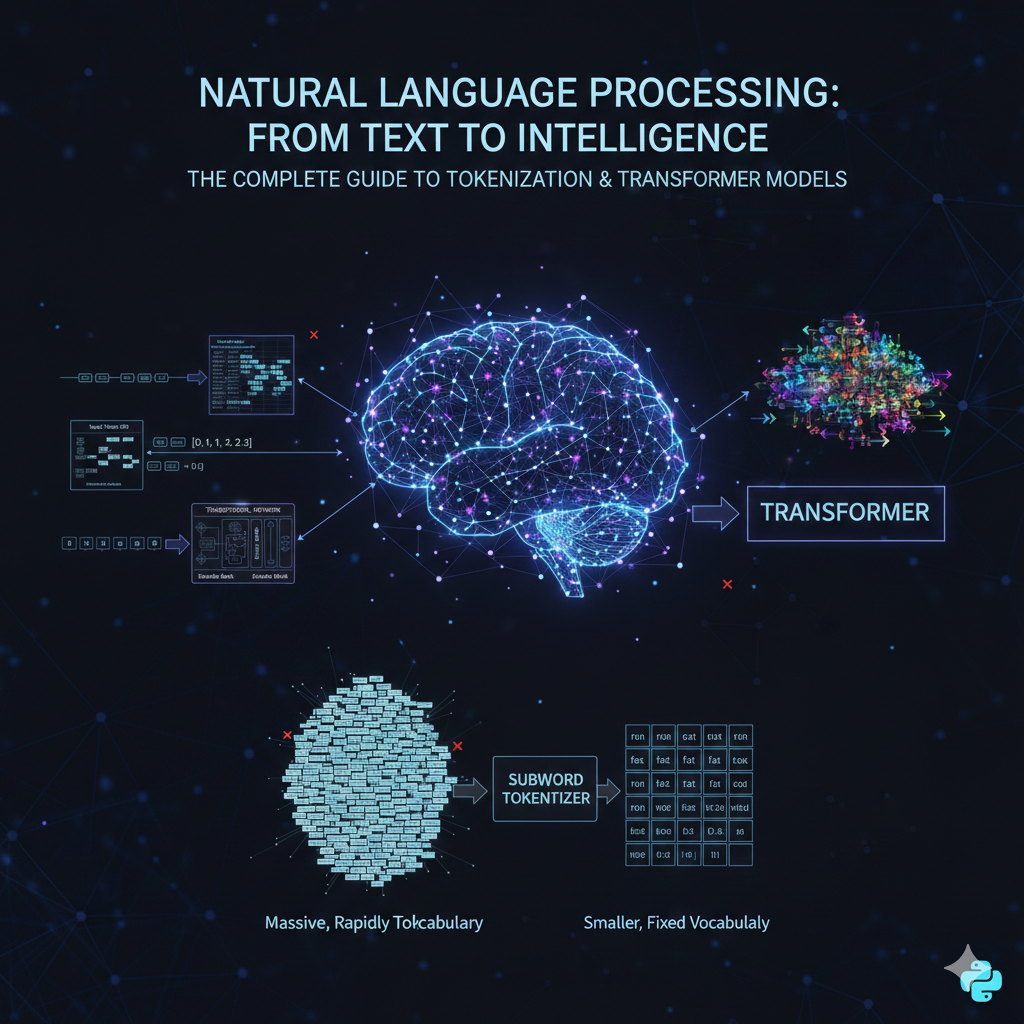
Natural language processing (NLP) uses mathematics to help computers analyze, interpret, and generate human language. From identifying a name in a sentence to translating a paragraph, NLP systems rely on mathematical models that turn words into data, find patterns, and estimate what language is likely to come next.
No single area of mathematics explains all of NLP. The field draws on linear algebra, probability, statistics, optimization, information theory, and graph theory. Together, these tools help transform language into representations a computer can work with.
Representing Words as Numbers
Computers cannot directly perform calculations on words, so NLP systems convert text into numerical forms. A simple method is a one-hot vector: each word in a vocabulary receives its own position, with a value of 1 at that position and 0 everywhere else. For example, in a vocabulary containing “cat,” “dog,” and “bird,” the word “dog” might be represented as [0, 1, 0].
One-hot vectors are easy to understand, but they do not express meaning or similarity. The vectors for “cat” and “dog” are just as different mathematically as the vectors for “cat” and “airplane.” Modern NLP often uses word embeddings instead. An embedding maps a word or token to a dense vector of real numbers, such as:
cat → [0.21, -0.47, 0.83, ...]
These vectors are learned from data. Words used in similar contexts often end up with similar representations. Their similarity can be measured with cosine similarity:
cosine similarity(a, b) = (a · b) / (||a|| ||b||)
Here, a · b is the dot product of two vectors, and ||a|| and ||b|| are their lengths. A value closer to 1 indicates that the vectors point in similar directions.
Linear Algebra and Neural Networks
Linear algebra is central to modern NLP because text representations, model parameters, and intermediate calculations are usually stored as vectors and matrices. A neural network transforms these representations through a sequence of mathematical operations.
A simplified layer might calculate:
y = f(Wx + b)
In this equation, x is the input vector, W is a matrix of learned weights, b is a bias vector, and f is a function that adds nonlinearity. The result, y, becomes an input to another layer or is used to make a prediction.
For language models, these computations are performed on tokens and their contextual representations. The same token can be represented differently depending on its surroundings. For instance, “bank” has different meanings in “river bank” and “bank account.” Context-sensitive representations help a model distinguish between them.
Probability: Choosing Likely Words and Interpretations
Language is uncertain. A sentence can have several possible continuations, and a word may have multiple meanings. Probability gives NLP systems a way to represent that uncertainty.
A language model estimates the probability of a sequence of tokens. Using the chain rule of probability, the probability of a sequence can be written as:
P(w₁, w₂, ..., wₙ) = P(w₁) × P(w₂ | w₁) × ... × P(wₙ | w₁, ..., wₙ₋₁)
In practice, a model predicts a probability distribution for the next token based on the preceding context. For example, after “The sky is,” a model may assign higher probabilities to “blue” than to “sandwich.” The model then selects a token according to a decoding strategy, such as choosing the most probable option or sampling among likely options.
Probability also supports classification tasks. A sentiment model might estimate the probability that a review is positive, neutral, or negative. A spam detector can estimate the probability that a message belongs to the spam category.
Statistics and Learning from Data
NLP models learn patterns from examples. Statistics provides methods for estimating those patterns and evaluating how well they generalize beyond the training data.
A training dataset may contain pairs of inputs and desired outputs, such as sentences labeled with their sentiment. The model uses these examples to adjust its internal parameters. If the training data is incomplete or unrepresentative, the model may learn patterns that do not hold for other users, topics, or communities.
Statistical thinking is also important when interpreting results. A model’s accuracy on one test set does not guarantee that it will perform equally well in every setting. Results can vary with language, writing style, domain, and the quality of the evaluation data.
Optimization and the Learning Process
Training a neural NLP model involves finding parameter values that reduce prediction errors. This is an optimization problem. A loss function measures the difference between a model’s predictions and the desired answers.
For a classification task, one common loss is cross-entropy:
L = -Σᵢ yᵢ log(pᵢ)
Here, yᵢ represents the correct label, and pᵢ is the model’s predicted probability for that label. The loss becomes larger when the model assigns a low probability to the correct answer.
Training algorithms use gradients to determine how model parameters should change to reduce the loss. Gradient descent updates parameters in the direction that lowers the error. Because modern language models can have billions of parameters, these updates require substantial computation and carefully chosen training procedures.
Information Theory and Language
Information theory studies uncertainty and information. In NLP, entropy measures how uncertain a model is about an outcome. If a model considers many next tokens equally likely, its uncertainty is high. If one token is much more likely than the others, its uncertainty is lower.
Perplexity is a commonly used measure of how well a language model predicts text. It can be interpreted as the model’s average uncertainty about the next token. Lower perplexity often indicates better prediction on a given dataset, but it does not necessarily mean that the model is more accurate, useful, or reliable for every real-world task.
Attention and the Transformer
Many current NLP systems use transformer architectures. A key component is attention, which lets a model weigh different tokens when building a representation of a particular token.
In scaled dot-product attention, the model compares queries and keys, then uses the resulting scores to combine value vectors:
Attention(Q, K, V) = softmax(QKᵀ / √dₖ)V
Q, K, and V are matrices called queries, keys, and values. The dot products in QKᵀ measure how strongly tokens relate to one another. The softmax function turns those scores into weights, and the weighted values provide context for the next computation.
Attention helps a model connect words that may be far apart in a sentence. In “The book that the students borrowed from the library was fascinating,” the model can use attention to help connect “book” with “was,” despite the words in between.
Why the Mathematics Matters
The mathematical foundations of NLP explain how language models represent text, learn from examples, and make predictions. They also help researchers diagnose problems. Linear algebra clarifies how representations interact; probability describes uncertainty; statistics helps assess evidence; and optimization explains how models are trained.
Still, mathematical sophistication does not guarantee perfect understanding. NLP systems can reproduce errors and biases in their data, struggle with unfamiliar contexts, or produce confident but incorrect responses. Their outputs are the result of learned statistical patterns, not proof of human-like comprehension.
Understanding the mathematics behind NLP makes it easier to see both what these systems can do and where they can fail. It also provides the tools needed to build, evaluate, and improve language technology responsibly.
7 Essential Math Tips for Mastering NLP
- Review linear algebra, especially vectors and matrices.
- Understand probability and conditional probability.
- Learn logarithms for loss functions and probabilities.
- Study gradient descent and basic optimization.
- Practice Bayes’ rule and statistical inference.
- Explore embeddings as geometric representations.
- Use information theory to understand entropy and cross-entropy.
Review linear algebra, especially vectors and matrices.
Reviewing linear algebra—especially vectors and matrices—is a valuable first step in understanding the mathematics behind natural language processing. NLP systems represent words, sentences, and model parameters as numerical vectors and matrices, then use operations such as dot products and matrix multiplication to compare meanings and process context. Familiarity with these concepts makes it easier to understand word embeddings, neural networks, and attention mechanisms.
Understand probability and conditional probability.
Understanding probability and conditional probability is essential in NLP because language models use them to estimate how likely words, phrases, or interpretations are. Conditional probability describes the likelihood of an event given relevant context—for example, the probability of the next word given the words that came before it. This idea underlies tasks such as text prediction, speech recognition, and machine translation. A solid grasp of probability helps you understand how NLP systems handle ambiguity, compare possible outputs, and make predictions under uncertainty.
Learn logarithms for loss functions and probabilities.
Learn logarithms to better understand how NLP models work with probabilities and loss functions. Logarithms turn products of probabilities into sums, making calculations more manageable and helping prevent extremely small values from causing numerical problems. They also appear in cross-entropy loss, which penalizes a model when it assigns a low probability to the correct answer. Familiarity with logs will make it easier to follow how language models measure uncertainty, evaluate predictions, and improve during training.
Study gradient descent and basic optimization.
Study gradient descent and basic optimization to understand how NLP models learn from data. Gradient descent adjusts a model’s parameters step by step to reduce its loss, while optimization concepts such as learning rate, convergence, and local minima explain how those updates affect training. A solid grasp of these ideas makes it easier to understand how neural language models improve their predictions—and why training can become slow or unstable.
Practice Bayes’ rule and statistical inference.
Practice Bayes’ rule and statistical inference to understand how NLP systems reason under uncertainty. Bayes’ rule shows how to update the probability of a hypothesis as new evidence becomes available—a useful idea for tasks such as classifying sentiment, identifying a word’s meaning from context, or filtering spam. Work through examples by calculating prior probabilities, likelihoods, and posterior probabilities, then compare your results with observed data. Regular practice builds intuition for how statistical evidence shapes NLP predictions and helps you recognize when limited or biased data may lead to unreliable conclusions.
Explore embeddings as geometric representations.
Explore embeddings as geometric representations by thinking of each word or phrase as a point in a multidimensional space. In this space, items with similar meanings or uses often appear closer together, while less related items tend to be farther apart. Try comparing vectors with measures such as cosine similarity, and remember that an embedding’s geometry reflects patterns in its training data—not a perfect map of meaning. This perspective makes concepts like semantic similarity, word relationships, and contextual representations easier to understand.
Use information theory to understand entropy and cross-entropy.
Use information theory to understand entropy and cross-entropy, two concepts that explain uncertainty in NLP. Entropy measures how uncertain a probability distribution is: when many outcomes seem equally likely, entropy is high; when one outcome is much more likely, entropy is low. Cross-entropy compares a model’s predicted probabilities with the actual data, assigning a larger penalty when the model gives low probability to the correct outcome. This makes cross-entropy a useful loss function for training language models and classifiers, while entropy helps describe how predictable language or a model’s predictions are.