Understanding the NLP Flow: From Raw Text to Useful Insights
Natural language processing (NLP) helps computers work with human language. It powers tools such as chatbots, search engines, translation services, and sentiment analysis systems. An NLP flow is the sequence of steps used to turn text or speech into information a computer can interpret—and, in many applications, a useful response.
The exact flow depends on the task. A translation system, for example, works differently from a tool that sorts customer feedback. Still, many NLP workflows share a common structure: collect language data, prepare it, analyze it, and use the results.
Define the task
Before processing language, a team needs to decide what the system should do. It might classify support requests, identify names and places, summarize a report, answer questions, or detect the tone of a review. A clear goal helps determine what data, methods, and evaluation measures the project needs.
Collect text or speech
The input may come from documents, websites, emails, chat messages, forms, or audio recordings. When the input is speech, an automatic speech recognition system may first convert the audio into text. Data should be gathered responsibly, with appropriate permissions and safeguards for personal or sensitive information.
Prepare the data
Raw language data can contain formatting issues, duplicated entries, spelling errors, or irrelevant content. Preparation may include removing unwanted markup, standardizing text, handling missing values, and separating the data into training, validation, and test sets.
Some workflows also use techniques such as tokenization, which breaks text into smaller units called tokens. Older or specialized systems may apply steps such as stemming or lemmatization to reduce words to simpler forms. Modern language models often handle many of these details through their own tokenization and processing methods.
Analyze the language
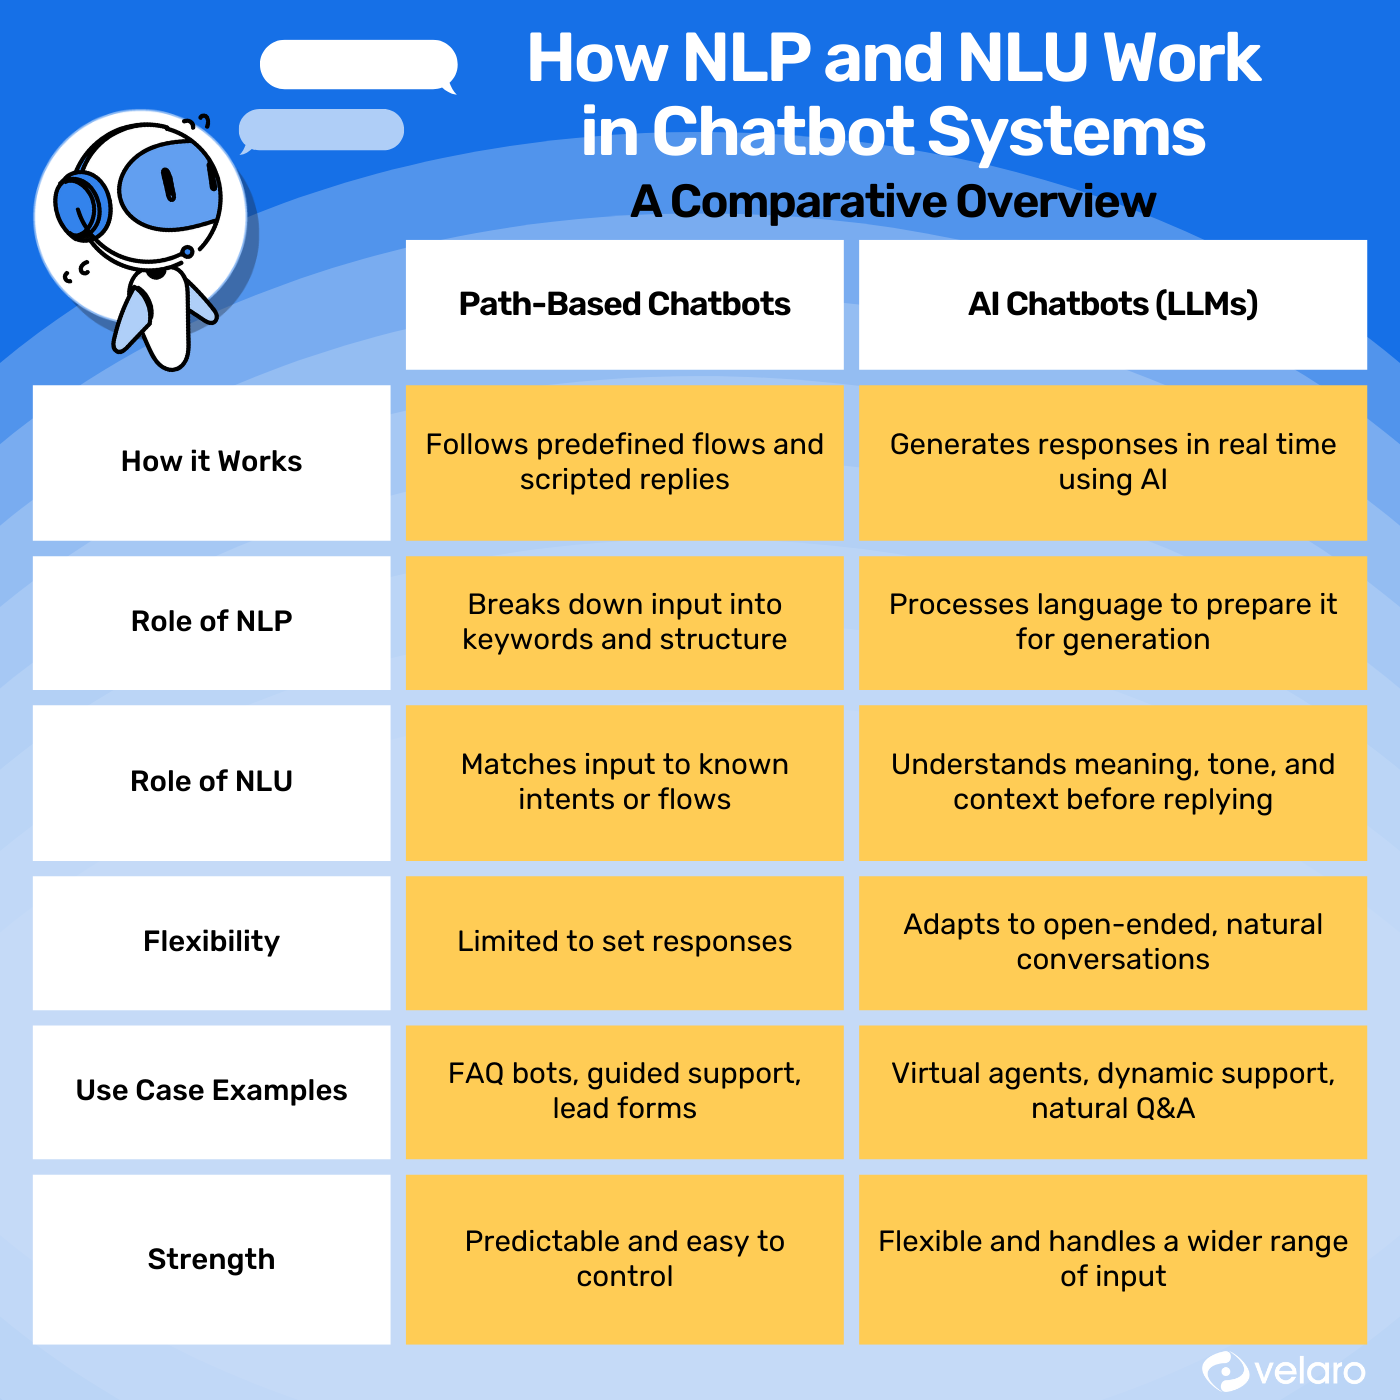
In this stage, an NLP method looks for patterns and meaning in the prepared input. The method could be a rules-based system, a traditional machine-learning model, or a large language model. The approach depends on the task, the available data, the required accuracy, and practical limits such as cost and processing time.
For example, a text-classification system may assign a message to a category, while an information-extraction system may identify dates, product names, or locations. A generative system may produce a summary or draft a reply.
Produce and deliver an output
The system’s result might be a label, a score, extracted information, a summary, or a response in natural language. The output can then be shown to a user or passed to another application, such as a customer-service platform or search system.
In higher-impact settings, it is often appropriate to include human review. A person can check uncertain or sensitive results before they are used to make a decision.
Evaluate and improve
An NLP flow does not end when a model produces an answer. Teams should test whether the system performs well on data it has not seen before. Evaluation measures vary by task: classification may use precision and recall, while generated text may require a combination of automated checks and human assessment.
Ongoing monitoring can reveal errors, changes in language use, or uneven performance across different groups. Based on these findings, teams can update the data, rules, prompts, or models and repeat the evaluation process.
A simple example of an NLP flow
Consider a company that wants to organize customer feedback. Its NLP flow might look like this:
- Collect comments from a feedback form.
- Remove duplicate submissions and irrelevant formatting.
- Classify each comment by topic, such as billing, delivery, or product quality.
- Estimate sentiment or flag comments that may need prompt attention.
- Send the results to a dashboard for staff to review.
- Check classification accuracy and refine the system as new feedback arrives.
Why the NLP flow matters
A well-designed NLP flow makes a language task easier to understand, test, and maintain. Breaking the process into stages helps teams identify where errors occur. For instance, a weak result may come from noisy input data rather than the model itself. A clear workflow also makes it easier to add privacy checks, human review, and quality controls where they are needed.
Common challenges
Language is complex. Words can have multiple meanings, people use slang and abbreviations, and the same idea may be expressed in many ways. NLP systems can also reflect gaps or biases in their training data. Privacy, security, cost, and response speed may be important considerations, too.
These challenges are best addressed throughout the workflow rather than at the final stage alone. Careful data handling, representative testing, transparent limitations, and ongoing monitoring can help make NLP applications more reliable.
Conclusion
The NLP flow is the path from human language to a result a computer can use. While the details vary by application, most workflows involve defining a task, preparing language data, applying an analysis method, delivering an output, and evaluating performance. Understanding each stage can help teams build NLP solutions that are more useful, responsible, and easier to improve.
8 Essential Tips for an Effective NLP Workflow
- Define the task clearly.
- Collect relevant text data.
- Clean and normalize text.
- Choose a suitable model.
- Split data for testing.
- Track key evaluation metrics.
- Review errors and edge cases.
- Iterate based on results.
Define the task clearly.
Define the task clearly before building an NLP flow. Decide exactly what the system should do—such as classify support requests, extract names and dates, summarize documents, or answer questions—and what a successful result looks like. A focused goal helps you choose the right data, model, and evaluation method, while preventing unnecessary complexity. It also makes it easier to spot errors and determine whether the system is meeting users’ needs.
Collect relevant text data.
Collect text data that closely matches the task your NLP system needs to perform. For example, if the goal is to classify customer support requests, use real examples of support messages across the topics the system will encounter. Choose reliable, representative sources, remove duplicate or irrelevant content, and make sure you have permission to use the data. Protect personal or sensitive information, and check the data for gaps or bias before using it.
Clean and normalize text.
Clean and normalize text before analysis to reduce noise and make language data more consistent. This may involve removing unwanted formatting, fixing encoding issues, standardizing whitespace, and applying consistent rules for capitalization, punctuation, or spelling. The right steps depend on the task: removing punctuation or stop words can help some workflows, but may erase useful meaning in others. Keep the original text when possible, and apply only the changes that support your NLP goal.
Choose a suitable model.
Choose a model that fits your NLP task, data, and practical requirements. A simple classification task may work well with a lightweight model, while translation or text generation may need a more capable language model. Consider accuracy, speed, cost, privacy, and the languages your application supports. Test a few suitable options on representative examples before deciding, and select the model that delivers reliable results without adding unnecessary complexity.
Split data for testing.
Split your data into separate training and testing sets so you can evaluate how well an NLP model handles text it has never seen before. Use the training set to teach the model and keep the test set untouched until evaluation; otherwise, the results may overstate how well the model performs on new examples. If your dataset is small or imbalanced, choose a split carefully so each set reflects the range of language and categories the model will encounter.
Track key evaluation metrics.
Track key evaluation metrics throughout your NLP flow to understand how well your system performs and where it needs improvement. Choose measures that match your task—for example, precision and recall for classification or human ratings for generated text—and monitor them on data that reflects real-world use. Reviewing these results regularly can help reveal errors, performance gaps, or changes over time, so you can make informed updates to your data, model, or workflow.
Review errors and edge cases.
Reviewing errors and edge cases is essential for building a reliable NLP flow. Examine examples the system gets wrong, such as slang, misspellings, ambiguous wording, rare terms, or unusually formatted input, and look for patterns behind those failures. Testing these cases helps reveal whether the issue comes from the data, preprocessing, model, or evaluation criteria. Use what you learn to improve the workflow, then test again to make sure the changes help without creating new problems.
Iterate based on results.
Iterate based on results. An NLP flow rarely works perfectly on the first try. Review how it performs in real-world use, look for recurring errors or gaps, and use that feedback to improve the data, rules, prompts, or model. Then test the updated flow to confirm that the changes help without creating new problems. Regular iteration keeps an NLP system useful as user needs and language patterns evolve.